Live Webinar

Failover Is Failure.

It waits for something to break, then breaks everything else on the way over.

If you have watched a VPN drop, a call die or a dispatcher lose a radio channel because a link switched over, you already know. In 45 minutes we take a failover event apart, stage by stage, and show what replaces it.

FeaturingContrivian Lighthouse™ and Contrivian NorthStar™

Save Your Seat

Date
Tuesday, December 1, 2026
Time
11:30 AM ET
Length
45 Minutes

Registration opens in Microsoft Teams. Can’t make it live? Register and we’ll send the recording.

2026, By the Numbers

$900K+

Cost of one hour of downtime for a Global 2000 company

43%

Of downtime incidents start in the network or IT environment, the largest single cause

47%

Of tech leaders say customers are often the first to notice an outage

57%

Of operators say their last major outage cost more than $100,000. One in five topped $1 million.

The Problem

Failover Fails Twice.

01

Your Users Feel It First.

The link degrades long before failover decides it’s dead. Calls break up, video freezes, and no alarm fires.

Gray failures often never trigger failover at all.

In 2026, 47% of tech leaders said customers are often the first to detect downtime. (Splunk)

02

Then the Switch Breaks Everything.

The backup brings a new public IP. Every open session, VPN tunnel, voice call and radio-over-IP channel drops.

When the primary comes back, it happens again.

Anatomy of a Failover Event

One Fiber Cut. Five More Problems.

A remote site loses its fiber and has cellular or satellite as backup. Timings vary by vendor. The sequence doesn’t.

Stage 01

Degradation

Link still “up,” dropping packets. Calls break up. No alarm.

Stage 02

Detection

Probes miss, hold timers count down. Dead air.

03 | Outage

Switchover

Public IP changes. Every open session drops.

Stage 04

Reconvergence

Tunnels rebuild. Users log back in. Some systems need a manual restart.

Stage 05

Running on Backup

Everything on a link sized as a spare. Uploads queue.

06 | Outage

Failback

Primary returns, IP changes again. A second outage.

Open sessions through one fiber cut With traditional failover, sessions degrade, stall during detection, drop to zero at switchover, run reduced on the backup link, and drop to zero again at failback. With Contrivian active-active, sessions stay up through every stage. Traditional failover Contrivian active-active OUTAGE 1OUTAGE 2 1 Degradation2 Detection3 Switchover 4 Reconvergence5 On Backup6 Failback One static IP. No session drops.

The fiber cut caused one problem. The failover design caused four more.

Why Adding Links Makes It Worse

Five Ways Failover Breaks.

687

Internet outages worldwide in a single week this September, 331 of them at ISPs. The links themselves aren’t getting more reliable. (Cisco ThousandEyes)

01

Detection Lag

Hold timers turn a one-second problem into many seconds of dead air.

02

The Session Reset

New link, new public IP. Everything tied to the old address breaks.

03

Flapping

LEO hands off every 30 to 90 seconds. Cellular swings minute to minute. Failover reads normal behavior as failure.

04

The Silent Backup

It carries nothing until the worst moment. Expired SIMs and lapsed contracts show up during the outage.

05

Failback

Going back to the primary is a second outage. Many teams just stay on the backup for days.

What Replaces It | Contrivian Lighthouse™

Every Link On. All the Time.

Contrivian Lighthouse bonds fiber, broadband, 5G, LTE and LEO into one connection. It measures every path every second and steers each application to the best one.

Everything sits behind one static IP that Contrivian owns, so a link can drop without anyone noticing.

Contrivian NorthStar shows the failed link to our NOC, and we repair it while you keep working.

Traditional failover compared with Contrivian active-active connectivity
CategoryFailoverContrivian Active-Active
LinksOne works, the rest waitEvery link carries traffic
TriggerAfter a link is judged deadSteers every second on loss, latency and jitter
Public IPChanges with each linkOne static IP, independent of any carrier
VPN, Voice, RoIPTear down and rebuildStay up through link loss and satellite handoffs
Spare Link HealthUnknown until neededProven every second under load
FailbackA second outageDoesn’t exist

Take It Home

Test Your Own Network.

Five tests to run at one of your sites with production apps open. Do them on your own, or with a Contrivian engineer.

Any dropped session means your network depends on failover.

01

Pull the primary during a live video call, VPN session and file upload. Time the recovery.

02

Check the public IP before and after.

03

Degrade it without killing it: 5% packet loss or 300 ms of latency. Does traffic move?

04

Flap it: drop and restore three times in two minutes. Count the outages users would see.

05

Audit the backup: when did it last carry production traffic?

Who You’ll Hear From

Your Speakers.

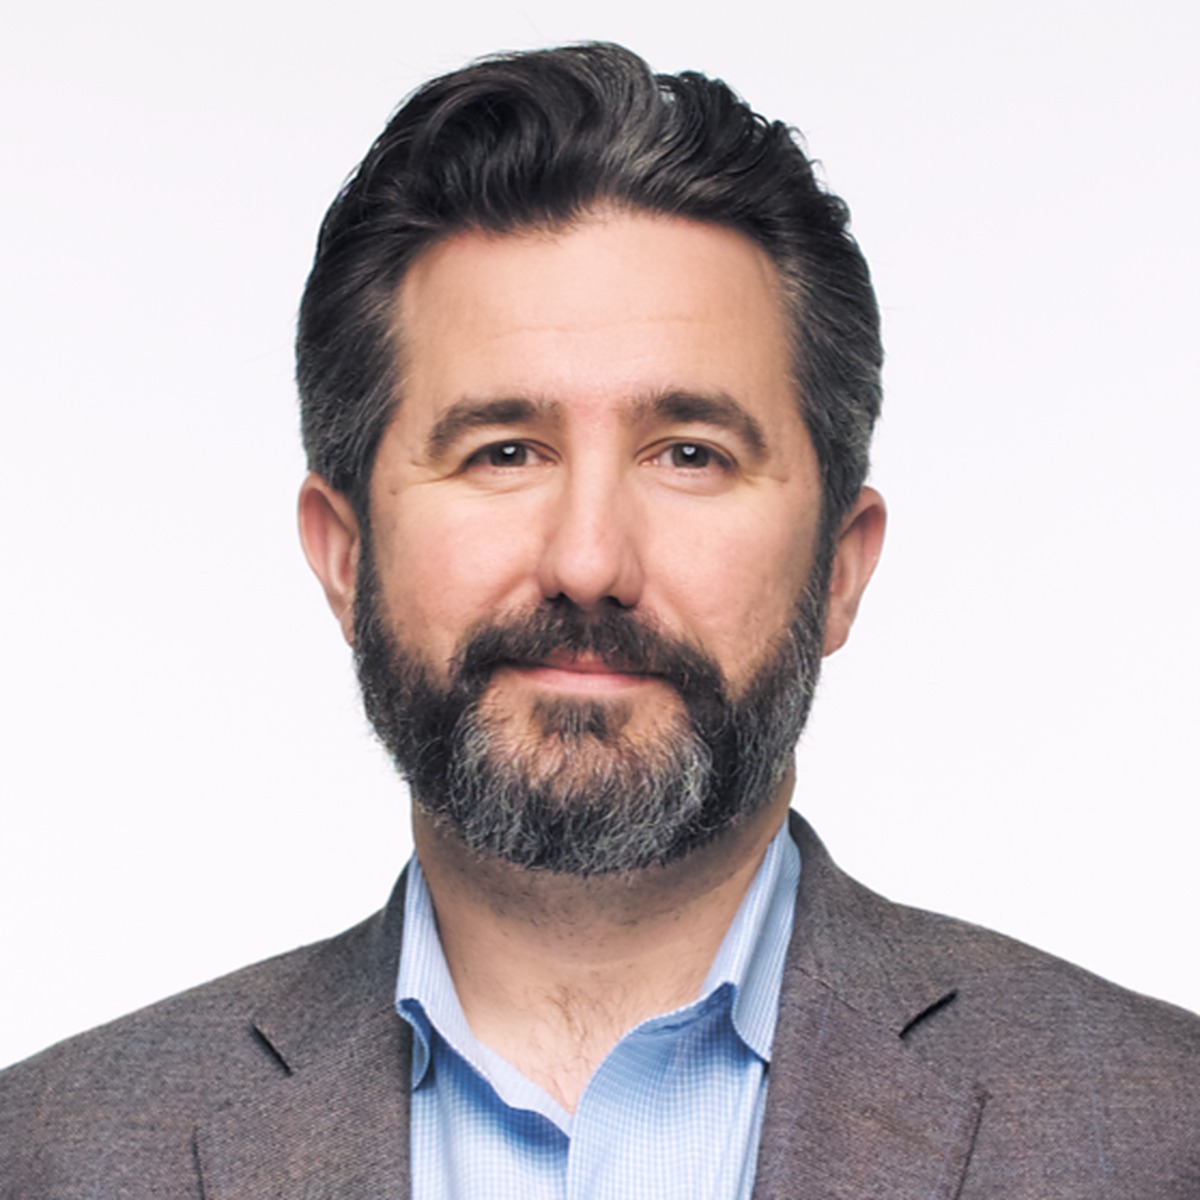
Tom Daly

Principal Technologist

Principal Technologist at Contrivian. Co-founded Dyn and ran infrastructure at Fastly, and knows more about your network than you know you don’t know.

Grant Kirkwood

CEO, Founder and Chief Plug‑Puller

Has a two-word opinion of failover we can’t print here. Tests his connectivity daily in the redwoods.

Matt Ray

CMO and Moderator

Keeps Tom and Grant on time. Mostly.

Gartner Eye on Innovation Award

Contrivian Lighthouse™

Contrivian NorthStar™

Contrivian Constellation™

Next Step

Stop Failing Over.

45 minutes. No fluff.
One test you can run on Monday.